Blog
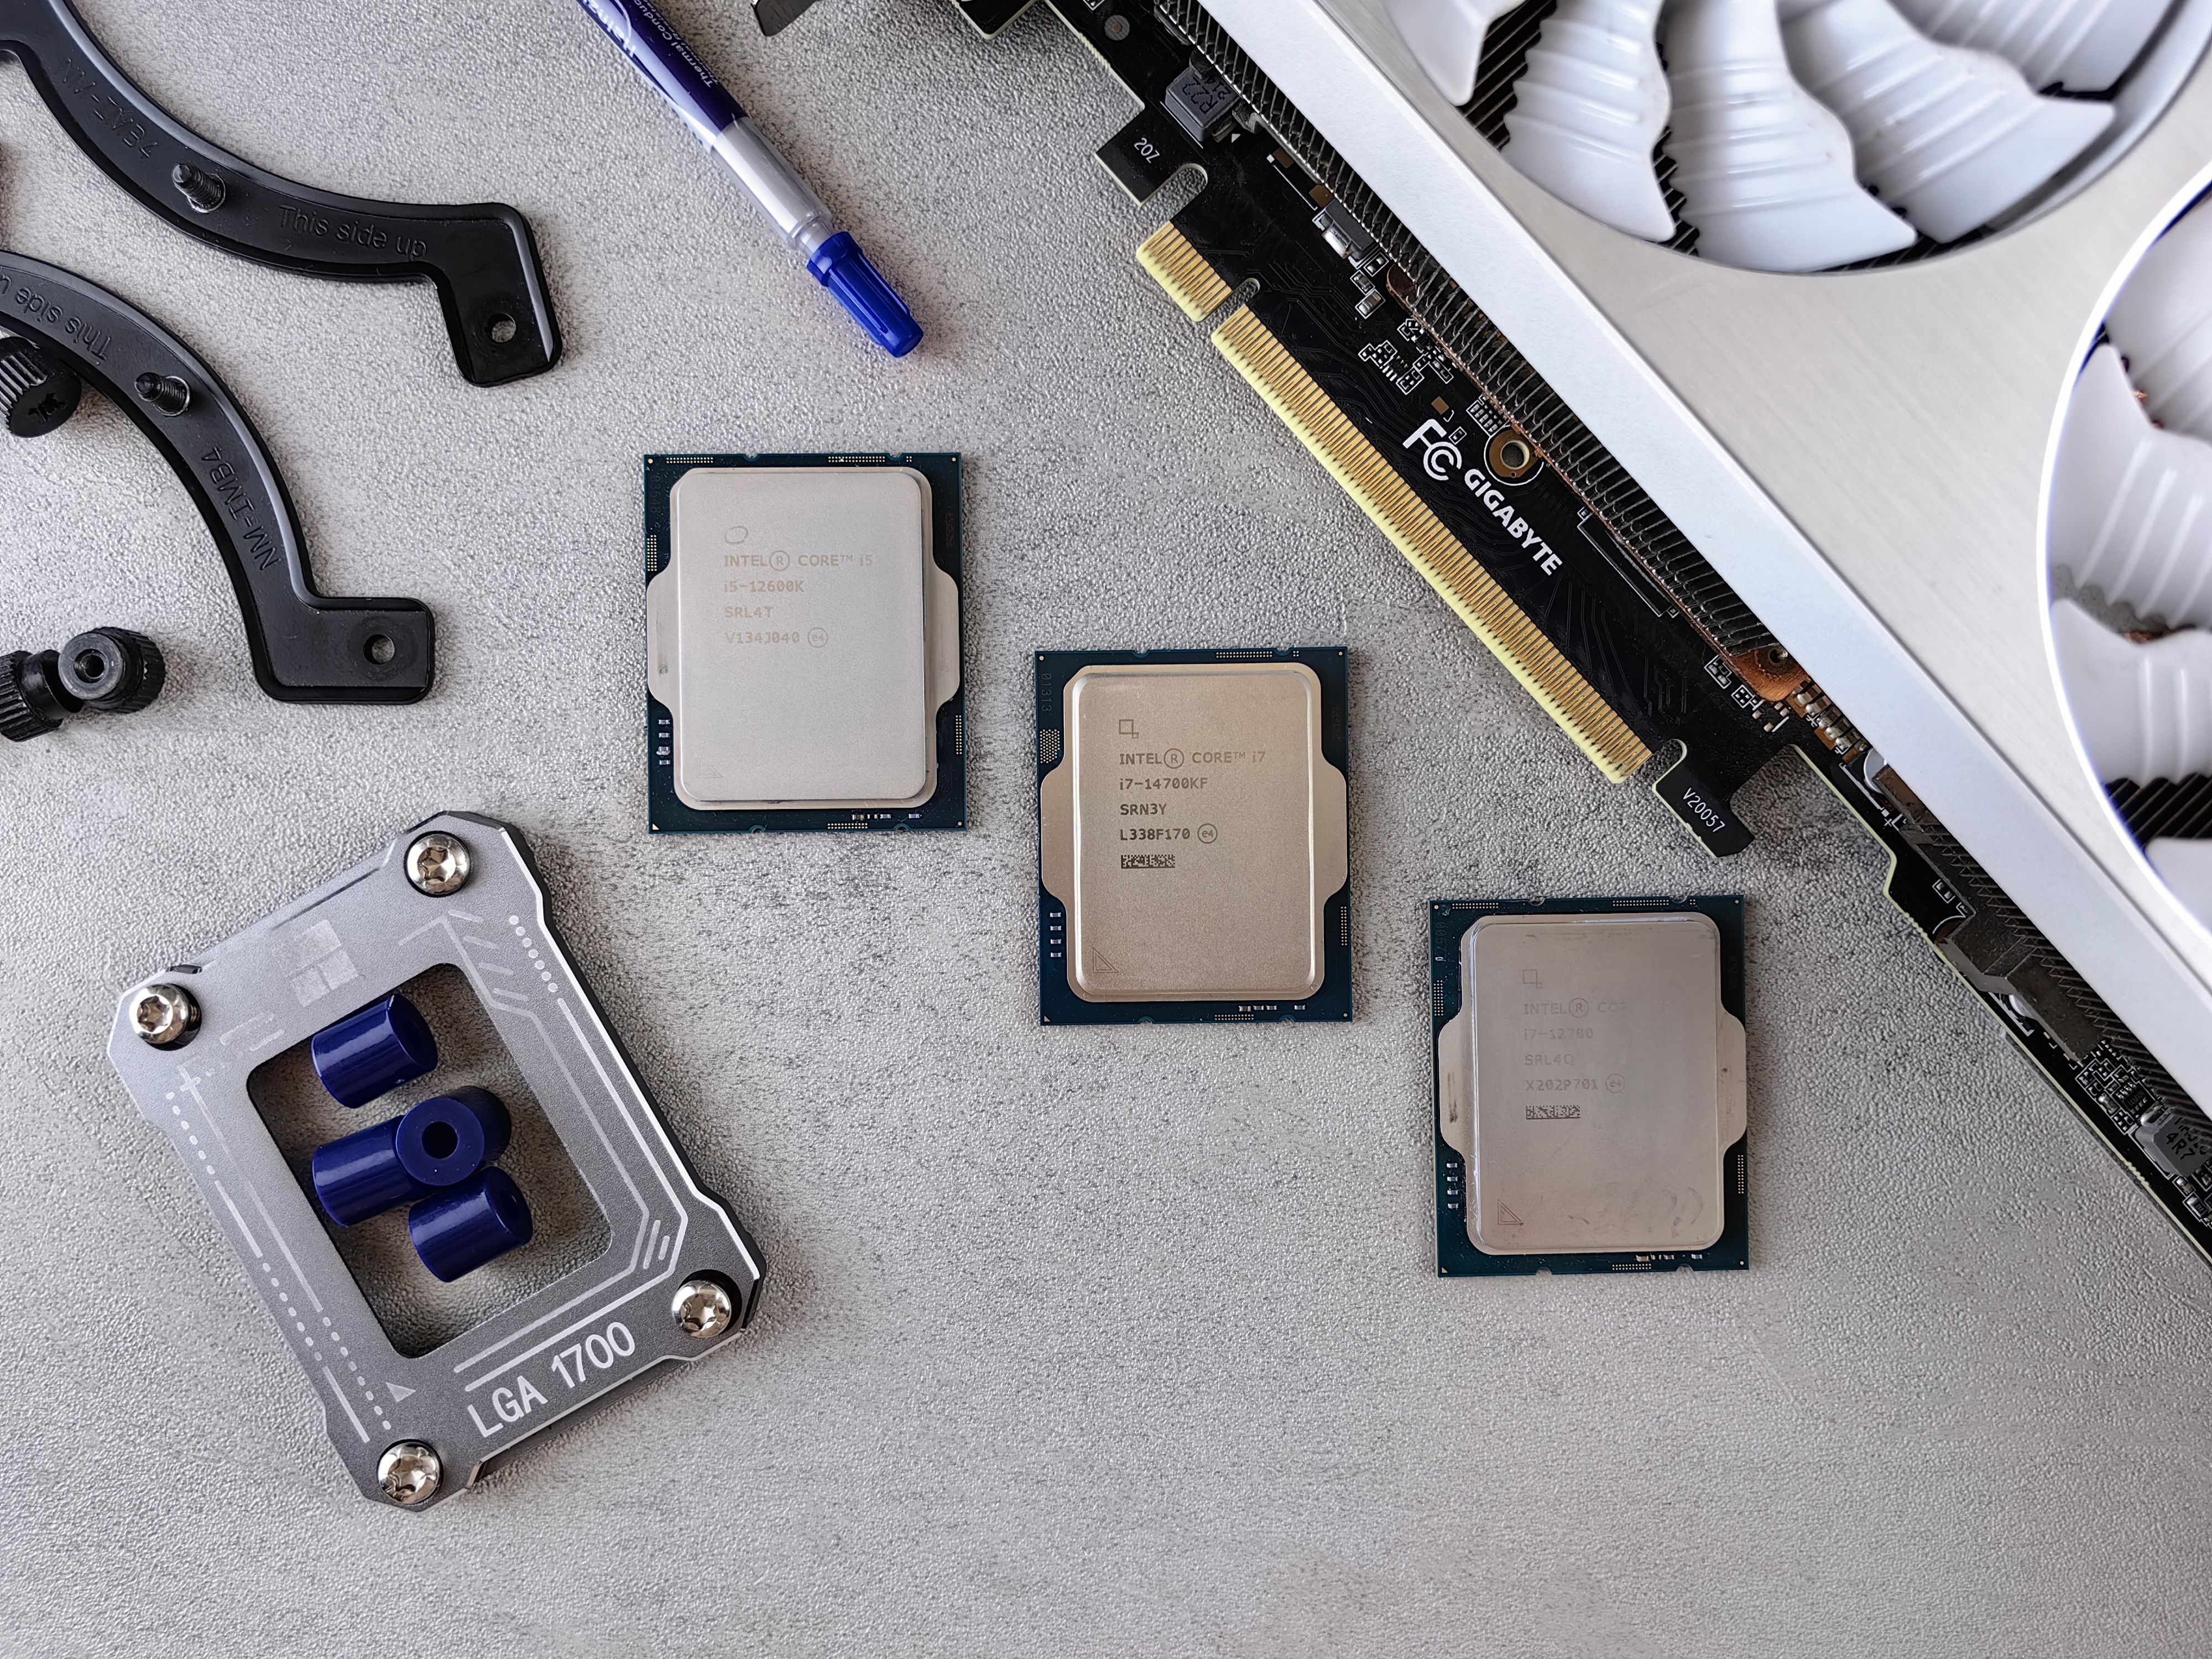
How we get our models running at full speed on Intel Xeon
Our own quantization and the Argon engine take an open 27B model to 30 tokens a second, on CPU.
Why general-purpose AI wastes most of what you pay for
Most automation needs a small part of what a general model can do. You pay for all of it.
AI now gives us an opportunity to do things correctly
A small model built for workflows can be checked, measured and trusted.